How to use
Preparation
Select the model architecture, whose performance you want to improve and the best training recipe for that architecture. Use an already trained model as the baseline. Start incorporating the custom ops of the GeoND library into the model architecture.
Configuring
When introducing a paraboloid neuron layer, it is very important to correctly configure it. Doing so involves selecting the correct values for the arguments input_factor, output_factor, grad_factor, h_lr_factor and p_lr_factor. This has to be done, so that the changes in the parameters of the paraboloid neuron layer are in-tune with the changes in the parameters of the rest of the model. Overestimating or underestimating these values can result in either the paraboloid layer or the rest of the network being unable to keep up with the intensity of the changes in the other. For the arguments input_factor, output_factor and grad_factor, the image below illustrates what they multiply and is meant to help users understand how changes in their values can affect preceding or proceeding layers:
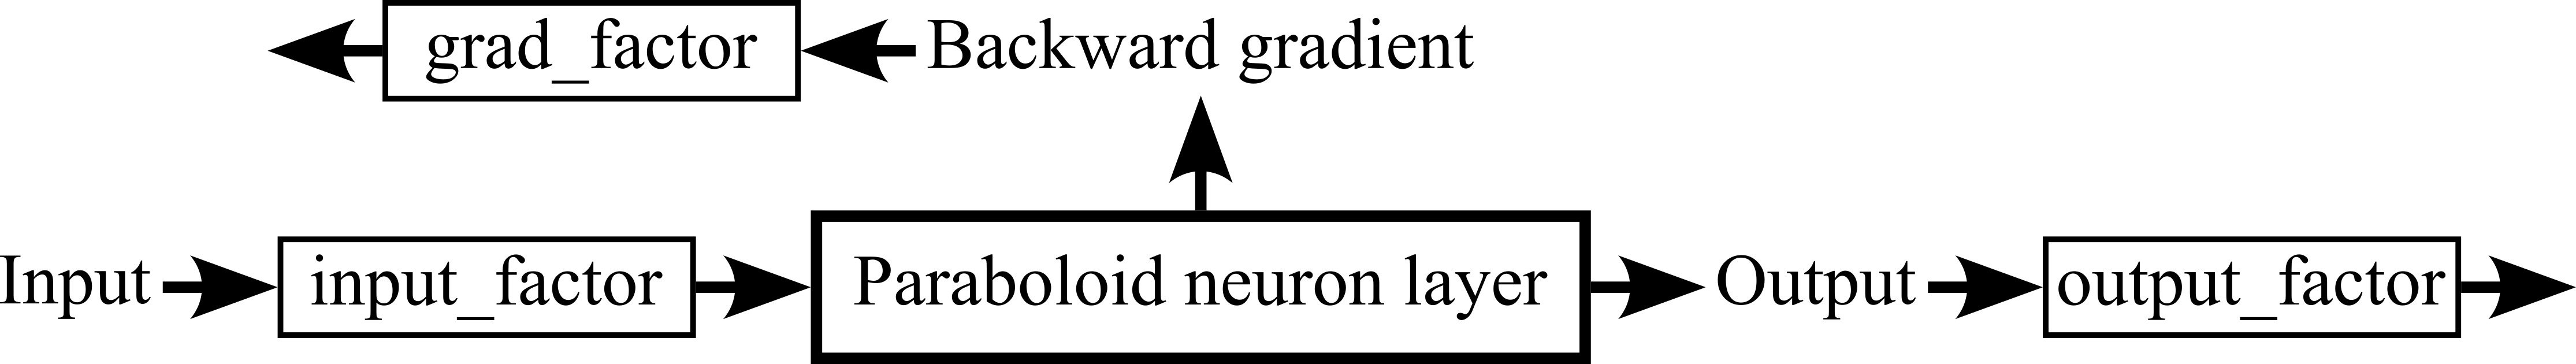
With respect to h_lr_factor and p_lr_factor, they should typically be equal and multiply the learning rate applied to the neuron layer parameters by the optimizer. Refer to the examples listed below to get an idea of how configuring works.
ParaboloidOutput
Replace a Linear output layer with ParaboloidOutput. See the Configuring section above. If using an SGD optimizer (GeoNDSGD), make sure to try setting momentum = 0.0 and nesterov = False, as the convergence is fast even without momentum. After you see how momentum = 0.0 performs, you can try increasing it, although too high values for momentum can result in decreased performance (e.g., in lightweight models). For example uses in CNNs, see Paraboloid neuron layers on CIFAR100 and Paraboloid neuron layers on Imagenet. Also see Fine tuning below.
Paraboloid
Replace a Linear layer with Paraboloid OR insert a Paraboloid layer before a Linear layer. See the Configuring section above. If using an SGD optimizer (GeoNDSGD), make sure to try setting momentum = 0.0 and nesterov = False, as the convergence is fast even without momentum. After you see how momentum = 0.0 performs, you can try increasing it, although too high values for momentum can result in decreased performance (e.g., in lightweight models). If using an Adam optimizer (GeoNDAdam or GeoNDAdamW), try different values for paraboloid_beta2 (documentation). For example uses in lightweight CNNs, see Paraboloid neuron layers on Imagenet. For an example use in LLMs, see Paraboloid neuron layers on TinyStories (note the use of ParaboloidBatched). Also see Fine tuning below.
ParaConv2d
Replace a Conv2d layer with ParaConv2d. Try using fewer convolution kernels (remember to also make appropriate changes to the next layer). Also see Fine tuning below.
Training
Make sure you are using the corresponing optimizer provided by the library (GeoNDSGD, GeoNDAdam, GeoNDAdamW). Follow the same training process as the baseline (dataset, input transformations, learning rate schedule etc). It is recommended that you use weight decay even if the original optimizer does not.
Fine tuning
Once a paraboloid neuron layer is correctly configured, you can try to further improve performance by changing the mom_factor and wd_factor that multiply the momentum term and weight decay term, respectively.
Evaluation
Compare the performance or speed of the new model with the baseline. If it is better or faster than the baseline, congratulations on your new model. Use this model as the new baseline and repeat the process, replacing another layer or adding a new layer in a different place.